Alibaba’s Qwen4-Max Claims 60% Cheaper Tasks, but the Proof Is Its Own Benchmark
The only disclosed basis we found is Work360, Alibaba's in-house test, where cost per task fell from 26.58 to 11.16 yuan, and the safety claims rest on Alibaba's internal testing.

Alibaba launched Qwen4-Max on Monday, with average task costs over 60% lower than Qwen3.8-Max. The 2.4-trillion-parameter model supports vision and a 1-million-token context window. It’s the kind of figure a finance team circles.
The disclosed evidence behind it is narrower than the headline suggests, and the safety upgrades Alibaba stresses are described in the company’s own terms.
For anyone deciding whether to move workloads, the useful question is what exactly got cheaper.
The 60% comes from one benchmark in one mode
The cut is tied to high-effort reasoning mode, where the model reportedly used 35% fewer tokens and cost about 60% less per task. Its headline gives no baseline.
The comparison is with Qwen3.8-Max and gives the only numbers: on Work360, cost per task dropped from $4.43 to $1.67, a 62% reduction.
However, Work360 is Alibaba’s own framework, covering 26 primary domains, 182 secondary ones, and 721 narrow directions.
So we have nothing about how “task cost” is defined, or whether the saving holds outside this test.
Nonetheless, the model ranks sixth on Arena AI’s coding leaderboard, beating Claude’s Fable 5.1, which was also pitched as cost-efficient.
Fewer tokens explain only part of the saving
Token efficiency metrics show cuts of about 48% to 49% on Terminal-Bench 4.0. Yet on Work360, tokens dropped 35% at high effort while overall task costs plunged 62%.
The gap means fewer tokens alone don’t tell the whole story. Cheaper tokens, cache hits, or both must account for the rest. No source gives the breakdown.
Official pricing lists input tokens at $1.50 per million and output tokens at $4.50 per million, as the company’s X post reads.
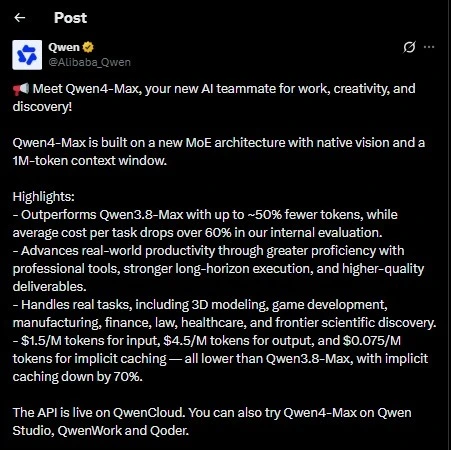
Meanwhile, cache hits drop to $0.075 per million tokens, a 70% discount over the prior generation. For workloads that repeatedly resend the same context, leaning heavily on cache hits will surely lower bills.
Under the hood, Qwen4-Max activates 71 billion parameters per token, representing a 25% reduction compared to Qwen3.8-Max at the same overall scale.
Access runs through QwenCloud, its Token Plan and API, and QwenWork and QwenStudio. Smaller open-weight Qwen4 models are promised in stages, with no dates.
Safety upgrades are described, not demonstrated
Alibaba says it integrated targeted security checks into its software engineering training, focusing specifically on code injection, memory-safety flaws, and broken access controls.
Training data underwent strict intent filtering, much like the domestic counterpart Moonshot AI’s Kimi K3.1 capability capping, retaining defensive vulnerability patches while removing offensive exploit content.
Additionally, dedicated datasets were incorporated to evaluate chemical, biological, radiological, and nuclear (CBRN) risks, with internal tests reporting no evidence of significant high-risk capabilities, per the blog.
Because these evaluations are entirely self-reported and leave terms like “significant” undefined, security teams face practical unknowns.
It remains unclear how the model handles legitimate penetration-testing requests. Alibaba’s showcase results, such as cutting manual workpiece programming time in an automotive demo from about 475 minutes to 24, are company-reported too.